Cerebras and OpenAI preview Ultrafast mode, running GPT-5.6 Sol up to 14x faster with no quality loss
Category: AI Infrastructure • Inference Speed
What it is
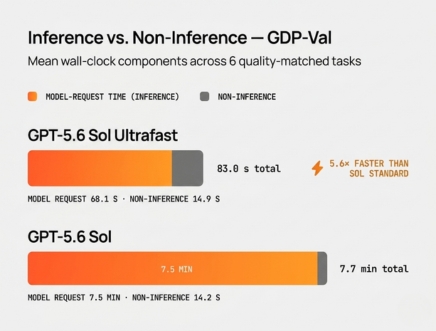
OpenAI and Cerebras previewed Ultrafast, a new API service tier running the full GPT-5.6 Sol model at up to 750 output tokens per second – up to 14x faster than Standard mode – via Cerebras’ wafer-scale chips, which keep weights on-chip to remove the memory-bandwidth bottleneck limiting GPU inference. On GDP-Val, a knowledge-work benchmark, it delivered a 5.6x end-to-end speedup with no quality drop, and completed the 2,500-question Humanity’s Last Exam in just over 11 hours, nearly 7x faster than Claude Fable 5. It launches first in the OpenAI API to a limited group of customers.
Why it Matters for Enterprises
Frontier-quality output at near-real-time speed opens latency-sensitive use cases like live incident response and interactive agents. Enterprises with time-critical workflows should join the preview waitlist to evaluate fit early.